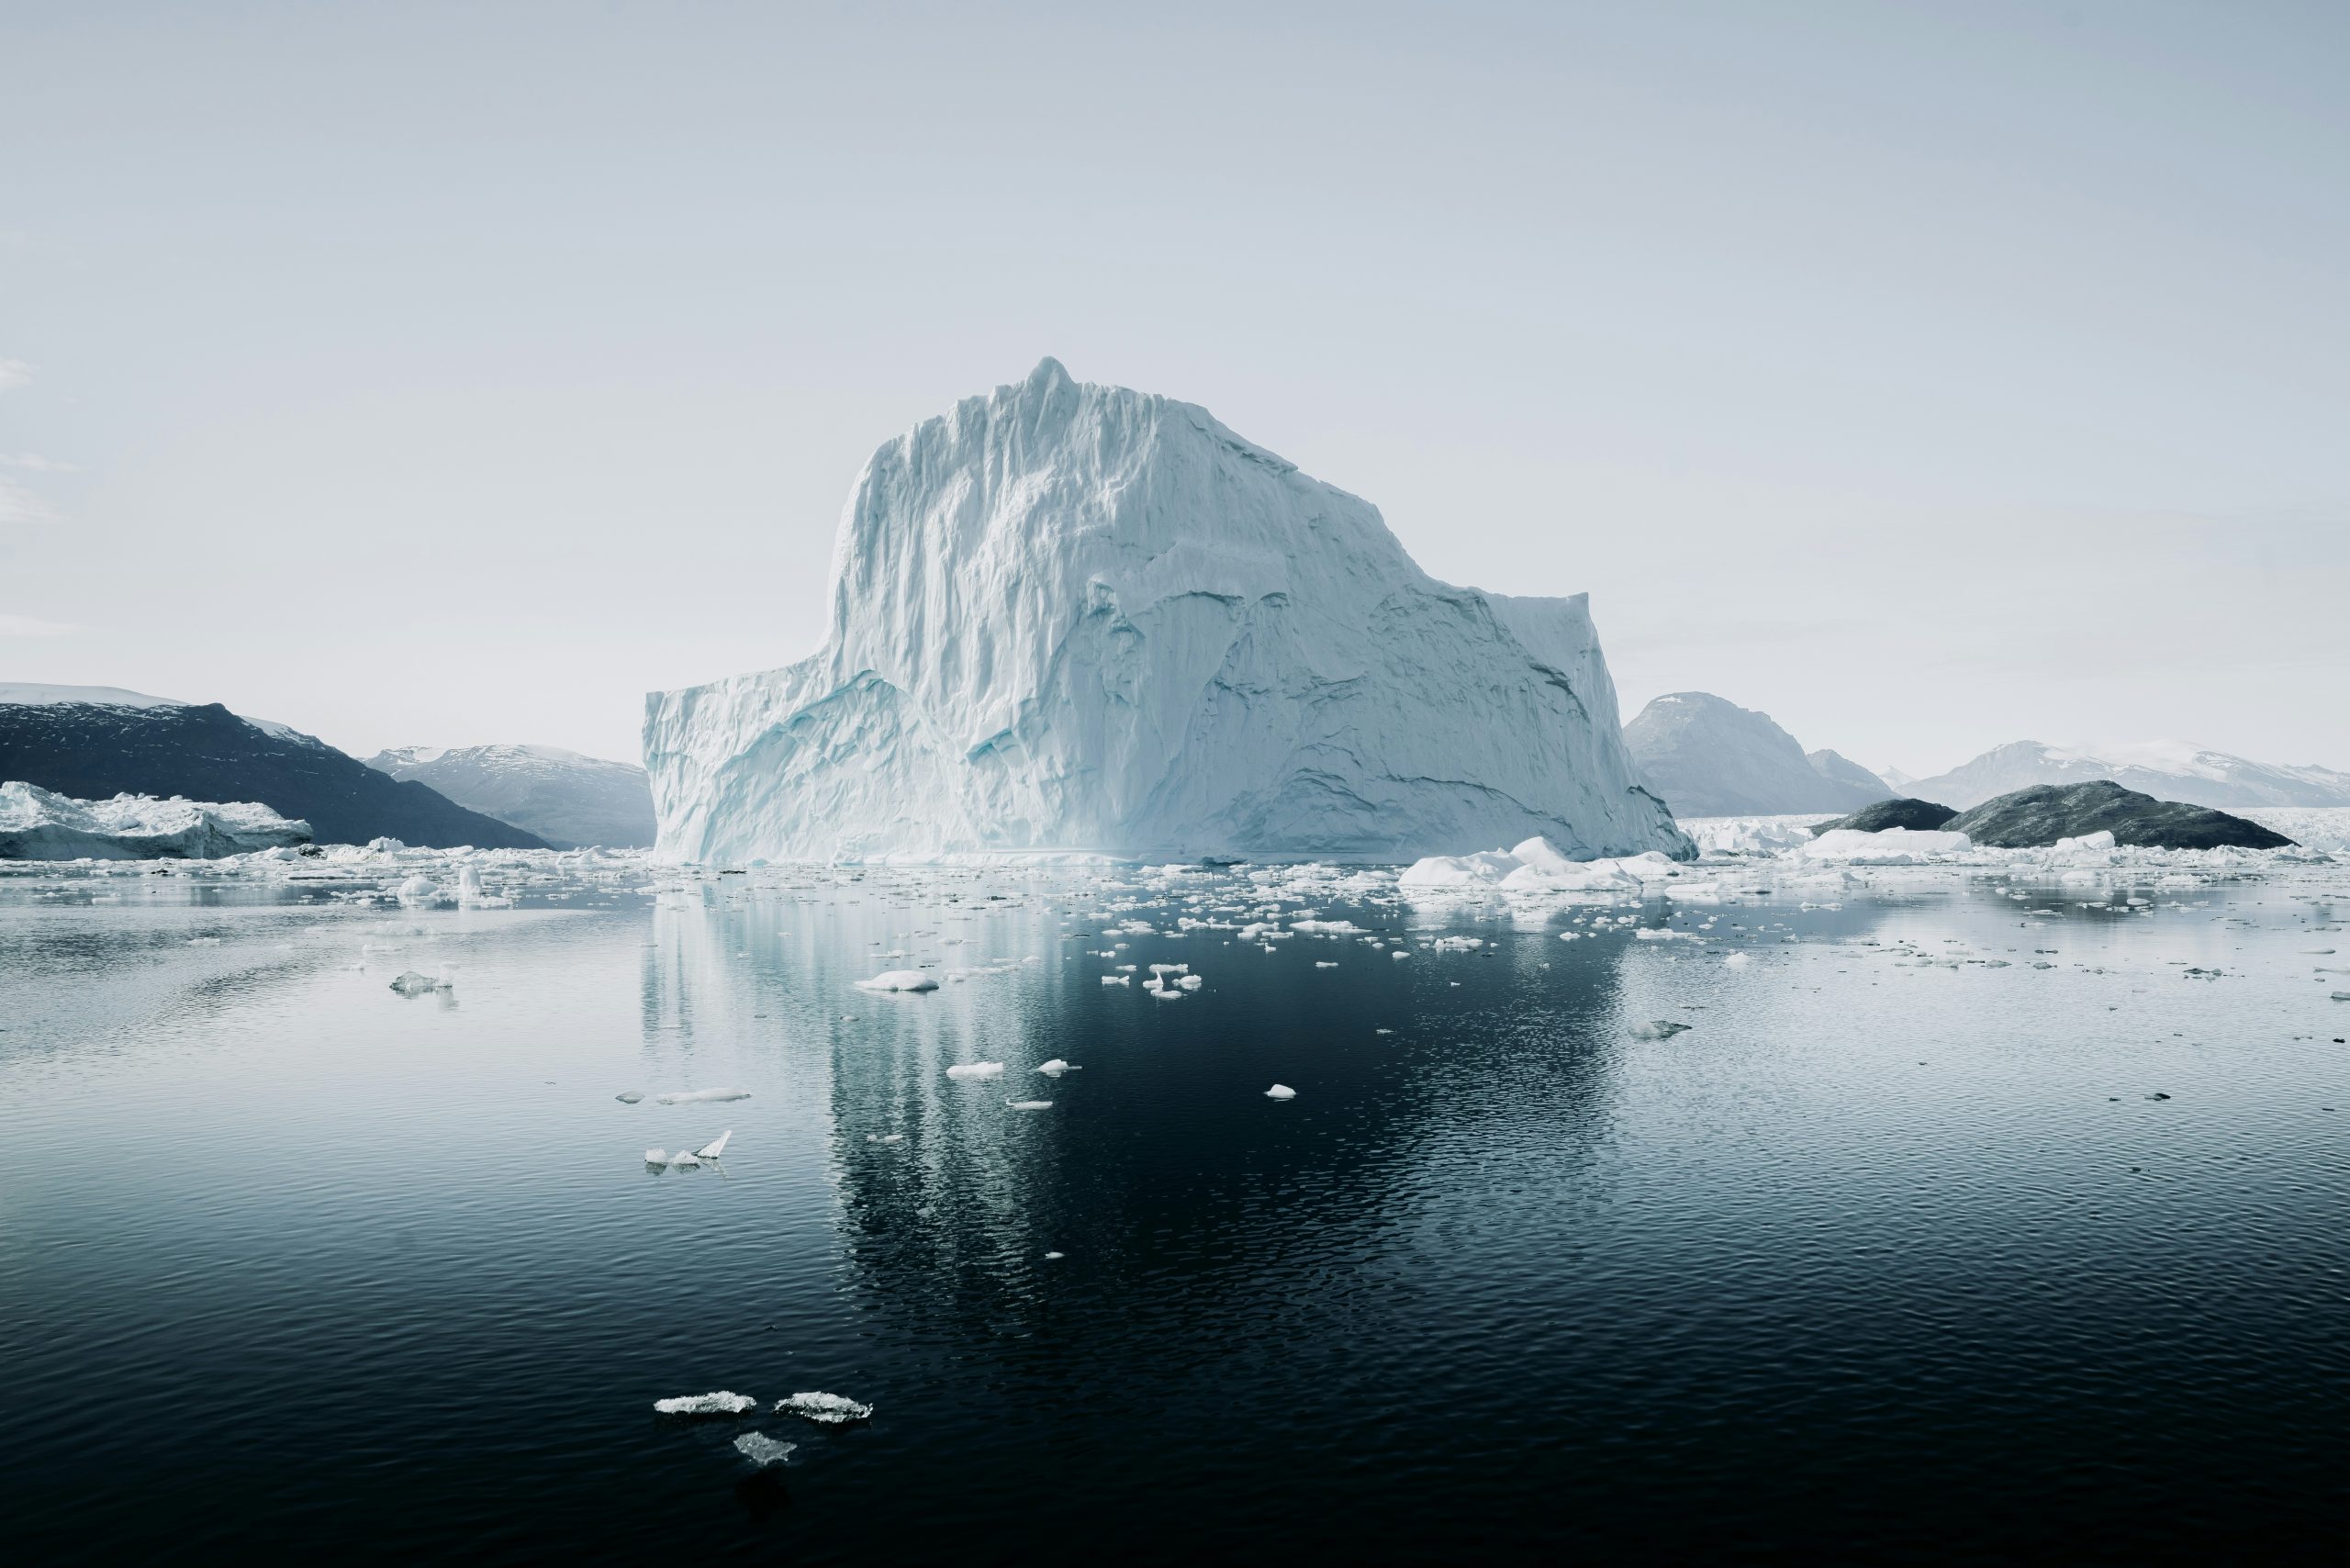
A familiar objection is often raised against paid regulatory intelligence: why pay for something that sits on a regulator’s website? It is a reasonable point. Regulations, enforcement notices, consultation papers and speeches are publicly available, and placing them behind a login does not make them proprietary.
According to Corlytics, yet those published documents are only the visible tip of a much larger structure. On their own, they are raw material. The real difficulty lies not in accessing information, but in interpreting it at scale and with lasting accuracy.
Below the waterline sits a substantial and largely unseen infrastructure. Content must be gathered daily from hundreds of regulatory, supervisory, legislative and enforcement bodies across many jurisdictions, each publishing in different formats, structures and languages. Collecting it reliably is merely the starting point.
Every document must then be followed through its lifecycle. Rules move from draft to consultation, through amendment and on to final publication, while guidance is revised and requirements are repealed or replaced. Without strict version control, firms risk relying on outdated obligations or being unable to prove which version applied when a decision was taken.
This is a real-world issue. In its 2021 review of data collection, the Bank of England found that firms struggled to locate the latest reporting instructions and all related documents. Participants described understanding those instructions as ‘one of the biggest sources of avoidable cost’. Although the review focused on regulatory reporting, it shows how much effort remains once material has been published.
Context is equally important. Metadata classifies content by jurisdiction, regulator, topic, sector, obligation, risk area and business function. Entity resolution connects references to organisations, legislation, products and market participants, recognising when different names or abbreviations point to the same thing. Taxonomies give users a consistent structure for searching, rather than depending on the wording of individual documents.
Technology carries much of this load, but human experts remain essential. They validate classifications, resolve ambiguity, monitor quality and correct errors, while AI models are continually trained, tested and refined for accuracy and explainability.
The Financial Conduct Authority captured this balance in its account of a TechSprint on machine executable regulatory reporting, describing the potential for “removing ambiguity – but not judgement”. Although the exercise covered only a small set of reporting rules, it showed what automation could achieve while accepting that firms must still apply judgement.
Crucially, this capability compounds. Each new document, link, classification and expert correction strengthens the intelligence layer. Historical data explains how requirements evolved, and the connections between documents make that history easier to trace.
That is why replication is far harder than it looks. A document downloads in seconds, but a trusted intelligence layer demands years of investment in acquisition, content management, domain expertise, taxonomy design, quality control and AI. It is not a weekend scraping project, and the work never stops, because the rules keep changing.
Read the full Corlytics post here.
Copyright © 2026 RegTech Analyst
Copyright © 2026 RegTech Analyst